AI solutions and LLM integration
We build AI solutions connected to company applications and data. The BRD project presents a knowledge-base assistant; answers are evaluated against relevant questions and available sources.
Trusted by founders, scale-ups & enterprise teams

 Anteca
 AI Automation
BRD: an AI assistant for banking knowledge
An assistant that connects questions with information from a banking knowledge base.
Read the case studyConsultDesignBuildRun
We help you define the solution, build it and support it after launch. For requirements and architecture, explore Product Discovery & Solution Blueprint or AI consulting and solutions. Together, we agree where to start and how to deliver.
Production AI capabilities, end to end
AI integration into existing systems
We embed AI capabilities into your existing ERP, CRM, internal apps and portals — without replacing the infrastructure you already run.
LLM product features & copilots
We design and ship LLM-powered features inside your product — chat interfaces, inline suggestions, document Q&A and domain-specific copilots — with latency and cost budgets set upfront.
RAG pipelines & knowledge bases
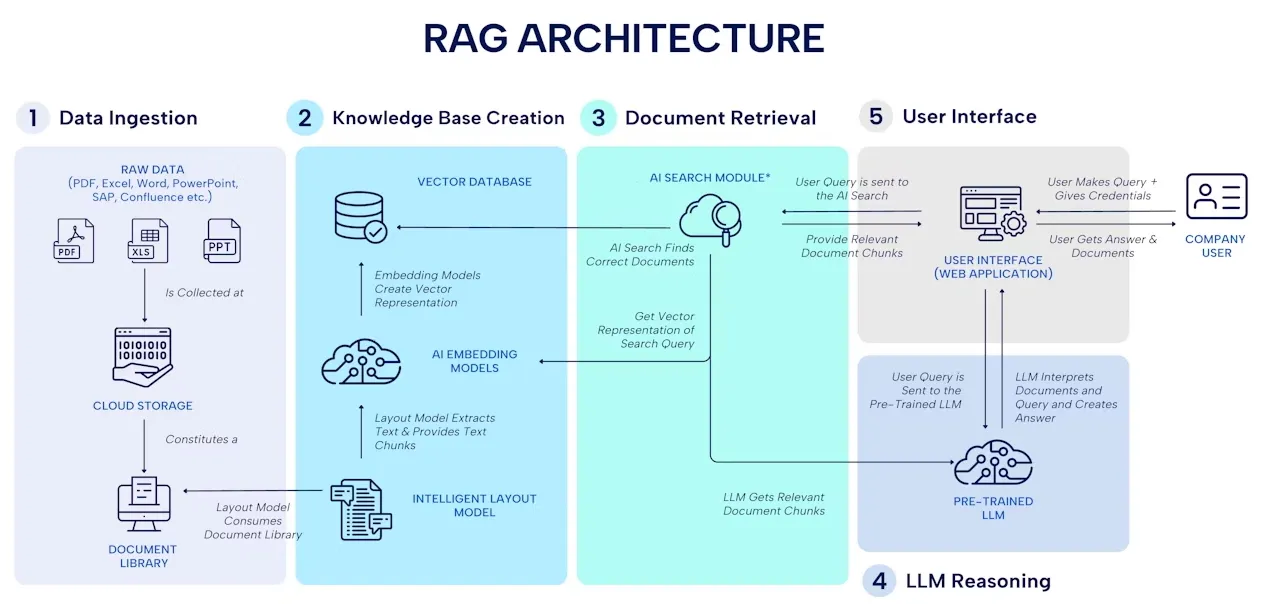
Retrieval-augmented generation systems that let your models answer from private data accurately — document ingestion, chunking strategy, embedding selection and retrieval ranking all owned by us.
AI agents & workflow automation
Multi-step autonomous agents that trigger actions, call external APIs and route between tools — built with observable traces so your team can inspect every decision the agent makes.
Evals, guardrails & monitoring
Systematic evaluation suites, hallucination guards and production dashboards that measure accuracy, refusal rates and cost over time — the reliability layer most AI projects skip.
Data pipelines & vector search
End-to-end data preparation — cleaning, transformation, embedding and indexing into vector stores — so the model always has fresh, relevant context to reason over.
AI strategy & build-vs-buy
An honest assessment of where a custom model or fine-tuned layer outperforms an off-the-shelf API — and where it does not. We help you invest AI budget where it compounds.
The AI stack we use in production
We work across the major model providers and orchestration layers — picking the combination that hits your accuracy, latency and cost targets, not the one that looks best on a slide.
Model choice, embedding strategy and vector store selection are engineering decisions, not vendor preferences. We benchmark before committing and re-evaluate as model capabilities change.
WhatsApp Business API & AI chatbots
UP2DATE is a Meta-verified Tech Provider for the WhatsApp Business Platform — so we can build and run AI assistants, automations and customer messaging on the official WhatsApp API, and onboard your business onto it properly. It is the same capability behind our auto-service ERP, where a WhatsApp AI bot answers customers 24/7.
See it in production — Service Auto ERPFrequently asked questions
Can we start without technical specifications?
Yes. We start with your business objectives and existing systems. We define requirements and architecture with your team, then deliver in stages. If the scope is already clear, we can start directly with implementation.
What can AI actually automate in my business?
The highest-value targets are usually repetitive information tasks: document review, data extraction, triage and routing, first-draft generation and customer-facing Q&A over private knowledge. The practical ceiling is determined by how much error you can tolerate and how much audit trail you need — we map this for your specific workflows in a discovery session before writing a line of code.
How do you prevent hallucinations in production?
There is no single switch — it requires layered defences. We combine retrieval-augmented generation (grounding answers in cited sources), structured output schemas (constraining what the model can say), confidence thresholds (routing low-certainty responses to a human), and a continuous eval suite that measures factual accuracy against a golden dataset you maintain. Monitoring in production catches drift before users notice.
Should we build custom AI or buy an off-the-shelf tool?
Buy for generic tasks where a SaaS product already covers 90% of your need. Build when your data is proprietary, your workflow is unusual, or the SaaS per-seat cost exceeds a custom build within 18 months. We run a structured build-vs-buy analysis early in every engagement — if the honest answer is "buy", we tell you before you pay us to build.
How do you handle our data privacy and GDPR?
We process your data under a data processing agreement aligned with GDPR. By default we use Azure OpenAI or self-hosted models so your data never trains a public model. For particularly sensitive domains — healthcare, legal, finance — we scope the architecture around on-premises or VPC-only inference from the start. Data retention policies and access controls are documented before any model sees production data.
What does an AI feature cost?
A focused LLM feature bolt-on — prompt design, retrieval layer, evals and monitoring — typically runs €20k–60k. A full agentic workflow with multiple tools and an observable trace layer is €60k–150k+. Ongoing model costs (API tokens or hosting) depend on usage volume; we estimate these during scoping so there are no surprises after launch. A discovery call gives you a first-cut range before any commitment.
Ready to ship production AI?
Start with a free 30-minute conversation about your goals and constraints. Detailed analysis, solution design and estimates are scoped separately.
Request an initial conversation
The first 30-minute conversation is free. We clarify your objectives, then propose a collaboration with clear deliverables, timing and costs.